Is Your Website Blocking Google or AI Search?
A useful page cannot compete in search if the crawler cannot reach its content. On a WordPress website, access problems can come from robots.txt, indexing settings, security plugins, hosting rules or Cloudflare. A page opening normally for you does not prove that Google or an AI search crawler receives the same response.
This guide shows you how to investigate those layers, identify the rule responsible and retest a small, reversible correction. It also explains how to restrict AI training while preserving the search access you want. Allowing access creates an opportunity to be discovered; it does not guarantee indexing, rankings or AI citations.
Start by deciding which access you want
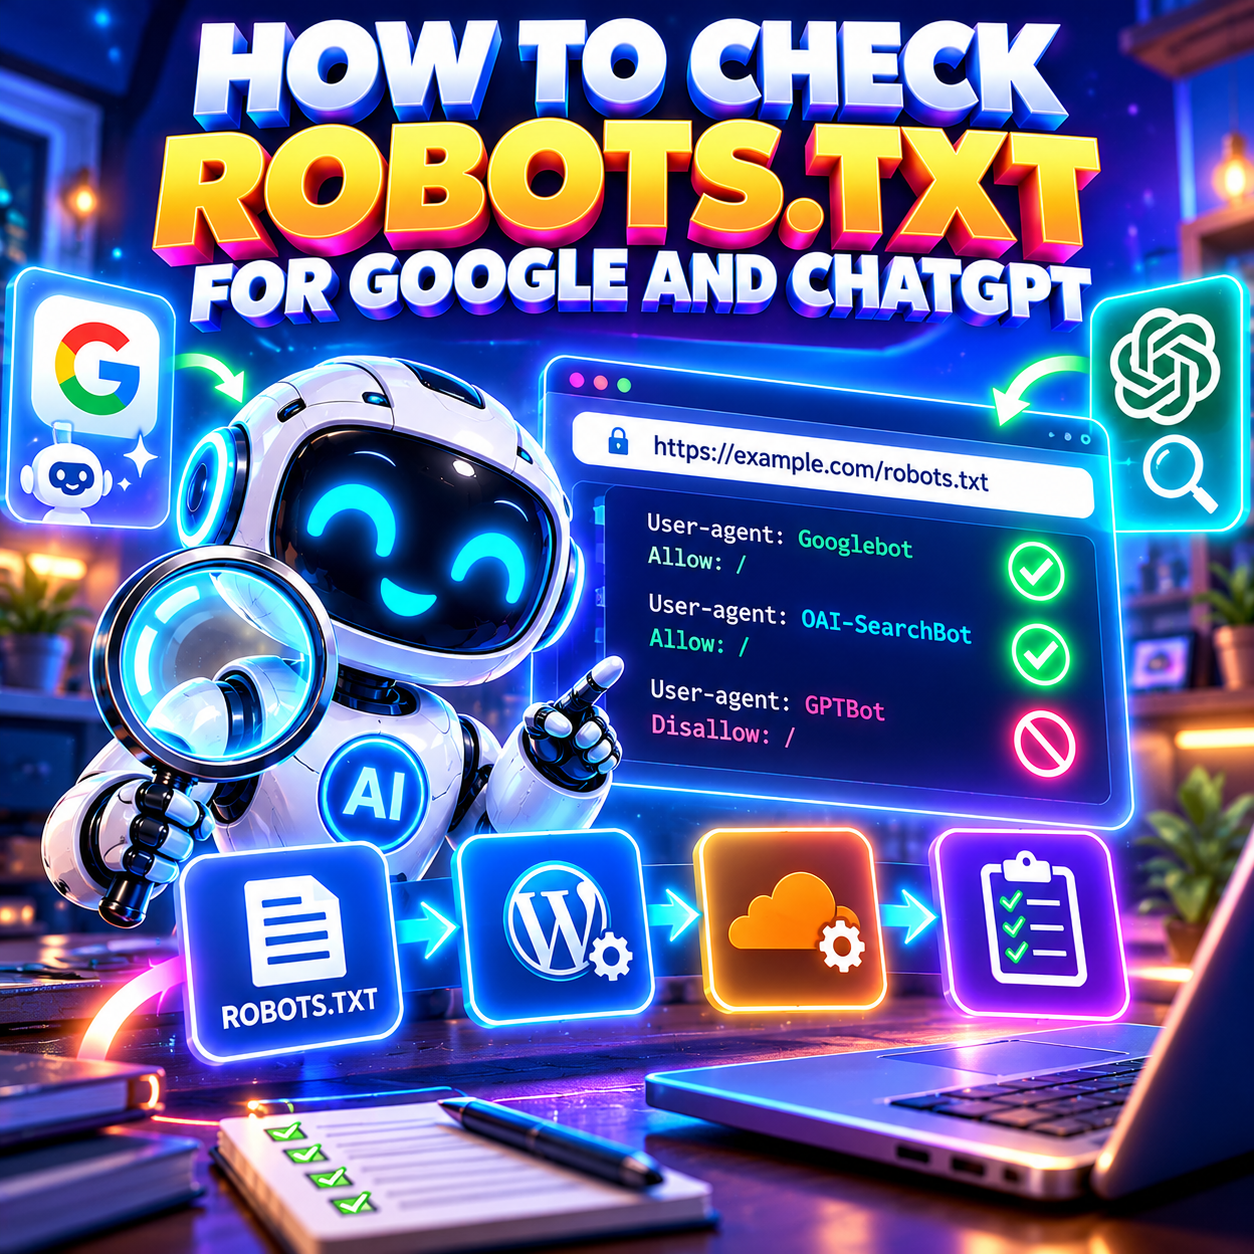
Search crawling, model training and user-directed page visits serve different purposes. Decide your policy before changing settings. For a typical local service business, that might mean allowing public service pages to be found in Google and ChatGPT search while declining training use where supported.
| Control or agent | Main purpose | What to check |
| Googlebot | Crawling for Google Search and its features | Can it fetch the public pages you want found? |
| Google-Extended | A use-control token for Gemini training and specified grounding uses | Treat this separately from Googlebot access. |
| OAI-SearchBot | Discovery for ChatGPT search | Allow intended public content if you want search inclusion. |
| GPTBot | Crawling content that may be used for OpenAI model training | Choose a training policy independently of search. |
| ChatGPT-User | Visits initiated by a user | This is separate from automatic search crawling. |
OpenAI documents OAI-SearchBot and GPTBot as independent controls. Opting out of OAI-SearchBot excludes sites from ChatGPT search answers, although navigational links can still appear. ChatGPT-User does not determine search inclusion, and robots.txt rules may not apply to its user-initiated visits.
OpenAI’s crawler purposes and published IP ranges
Google-Extended is not a separate HTTP crawler identity. It controls specified uses of content collected by existing Google crawlers, including Gemini training and grounding. Google states that it does not affect inclusion or ranking in Google Search. Blocking Googlebot itself is a different decision, affecting Search crawling.
Google’s crawler and product-token definitions
Prepare a small test and a rollback record
Choose the homepage, one important service or product page, one useful guide, and the contact page. Add the site’s robots.txt URL and sitemap. Use the real public HTTPS hostname, including www if that is your main address.
- Record the URLs, the symptom, when it started and any recent security or plugin change. A sudden traffic decline alone does not establish a crawler block.
- Copy the current served robots.txt text. Save the relevant WordPress setting and Cloudflare rule details, including the rule identifier, expression, action and enabled state.
- Confirm who can restore each setting. Make one change at a time and record its exact time so later requests can be compared with the earlier result.
Our example is a fictional garden maintenance business using WordPress behind Cloudflare. The owner wants Googlebot and OAI-SearchBot to reach its public service pages, while keeping its training restrictions. No private customer pages need to become public.
Step 1 Read the robots.txt visitors actually receive
Open https://example.com/robots.txt, replacing example.com with your own hostname. You should be able to read the response without logging into WordPress. Save that text before editing anything.
robots.txt gives crawling instructions to cooperating crawlers. It does not enforce access, protect confidential content or reliably remove a URL from Google’s index. Google can sometimes list a blocked URL without crawling its content. Private content needs proper access controls.
Google’s explanation of robots.txt and its limits
If you cannot find a file in File Manager
WordPress can generate a virtual robots.txt response, so there may be no physical file to find. Plugins can modify that output. Cloudflare can also add managed directives to the response served to visitors. The browser URL is therefore your starting point, rather than the hosting folder alone.
WordPress’s generated robots.txt output
Ask your website manager whether the response comes from a physical file, WordPress or a plugin, and whether Cloudflare modifies it. Edit the responsible layer. Creating a second physical file can replace the virtual response and lose existing rules or sitemap references.
Look for rules affecting important pages
This group asks cooperating crawlers covered by the wildcard group not to crawl the site:
User-agent: *
Disallow: /
Also check groups addressed to Googlebot and OAI-SearchBot, and restrictions covering your service or guide paths. A crawler-specific group can change the rules that apply to that crawler. Do not assume that one visible Allow line cancels every other restriction.
An isolated training restriction has a different purpose. For example, this group expresses a GPTBot opt-out:
User-agent: GPTBot
Disallow: /
It does not itself create an OAI-SearchBot block. Review the whole file before adding it, especially existing GPTBot groups and Cloudflare-managed sections. Keep rules for private or unimportant areas where intended. These fragments are examples to interpret, not complete replacement files.
Check the robots.txt response for each relevant hostname. A www host, a non-www host and a subdomain can have different configurations. If the response is an error or a security challenge, investigate that before assuming the written rules are being delivered correctly.
Google’s robots.txt grouping and hostname rules
Step 2 Check WordPress indexing and page settings
In WordPress, open Settings, then Reading. For a public website intended for search, check that “Discourage search engines from indexing this site” is unticked and save any intended correction. Keep development or private sites restricted.
In modern WordPress, this setting adds a noindex robots meta tag to normal page output rather than necessarily adding a site-wide robots.txt block. A permissive robots.txt therefore does not prove that indexing is allowed.
WordPress’s Search Engine Visibility setting
For each test page, check that it is published and publicly visible. In your SEO plugin, review its indexing setting and intended canonical URL. Check maintenance-mode and security plugins for public-page restrictions. Ask your site manager to inspect both page HTML and response headers if the source of a noindex instruction is unclear.
Treat crawling and indexing separately: a crawler can successfully download a page that is marked noindex. If robots.txt prevents the download, Google may be unable to see the page’s noindex instruction.
Step 3 Test a key page through Search Console
Open the correct Search Console property. Paste the complete page URL into the inspection bar. The initial result describes Google’s stored version, so note the last crawl and then select Test live URL to check the current page.
Review crawl permission, page fetch and indexing permission. If available, open View tested page to inspect the returned HTML, screenshot and resource information. Confirm that Google’s test sees your service content rather than a verification screen, empty layout or error.
Google’s URL Inspection instructions
Record the result for each test URL. A live test can establish that the inspection tool fetched a page; it does not guarantee indexing or search appearance. Google-InspectionTool is also distinct from ordinary Googlebot activity, so inspect actual crawler requests as well.
For Google’s AI search features, access is only part of eligibility. Google says the page must be indexed and eligible for a snippet, and the site must be included in generative AI features through Search Console. Check those requirements if access succeeds but AI visibility remains absent.
Google’s requirements for generative AI search
Step 4 Find blocked or challenged requests in Cloudflare
Select the correct domain in Cloudflare. In the current security dashboard, open Analytics and use Events for security actions; older navigation may call this Security Events. Traffic shows the broader request view, including requests without a security event.
Cloudflare’s current Security Analytics navigation
- Choose a short time window around a failed test or recent crawl.
- Filter by the affected hostname and path. Inspect Block and challenge actions, then relevant user agents or source IP addresses.
- Expand a matching event. Record the time, path, action, rule and service responsible. Retain the Ray ID when available to help your host or developer investigate.
- Compare the event with your page test. A security rule matching the same failed request is stronger evidence than a general count of blocked bots.
Security events are not unique requests: one request can trigger several events. Results may be sampled, especially on the Free plan. Narrow the time window if needed, and use hosting logs when the dashboard cannot establish what happened.
Cloudflare’s Security Events filters and limits
Recognise a challenge response
A “verify you are human” page can substitute for your content. Your own browser may pass the challenge and keep a clearance cookie, while an automated request receives the interstitial screen. Recheck in a fresh private window, but use crawler evidence to establish crawler access.
For a developer inspecting responses, Cloudflare documents the cf-mitigated header with the value challenge as an indicator of a Challenge Page. That is useful evidence alongside the returned HTML and matching security event.
Cloudflare’s Challenge Page response indicator
Do not accept a successful-looking HTTP code alone as proof that the right content was returned. Check the body and required resources. A broken server response or WordPress error can also prevent access without a Cloudflare block.
Step 5 Review AI crawler controls and training policy
In AI Crawl Control, inspect the crawler list and current actions. Review OAI-SearchBot separately from GPTBot. On the Free plan, Cloudflare’s documented identification relies on self-identifying user-agent strings, so treat the displayed label as evidence to investigate rather than independent proof of identity.
Cloudflare’s crawler actions and detection limits
Use the analytics date, hostname, path and crawler filters to inspect your test pages. Compare successful requests with redirects, client errors and server errors. Unsuccessful requests can come from other rules or errors, not just the crawler’s selected action.
Cloudflare’s AI traffic metrics
An Allow setting in AI Crawl Control does not override every other security rule. If OAI-SearchBot is allowed there but remains blocked, trace the matching WAF rule or hosting restriction instead.
How AI Crawl Control interacts with Cloudflare WAF
Understand Disallow AI Training before changing it
On 15 September 2026, Cloudflare announced Disallow AI Training for mixed-use crawlers. With Bot Preference Sync, it publishes applicable training preferences while preserving search access for accountable mixed-use crawlers. Other training crawlers, including OpenAI’s training-only crawler, are blocked.
Training Block and Block on pages with ads now include mixed-use crawlers such as Googlebot and Bingbot, so these settings can affect search access. This is why a blanket statement that every training restriction blocks Google is wrong: the selected action matters.
Cloudflare also notes a current Bing limitation: automatic robots.txt communication of its no-training preference is targeted for early 2027. Disallow AI Training does not yet automatically convey that preference to Bing. Check Microsoft’s separate controls if that is part of your policy.
Cloudflare’s mixed-use crawler announcement and limitations
Check the current dashboard settings
For a policy of allowing search while restricting training, open the domain’s Security Settings, filter by Bot traffic and select Configure AI bot policies. Check Search is Allow. For Training, select Disallow, turn on Enable Bot Preference Sync and select Save. Choose Agent separately according to your policy.
The interface’s Training Disallow corresponds to the announcement’s Disallow AI Training. Cloudflare’s current documentation says this adds managed robots.txt directives and blocks training crawlers at the edge, with mixed-use crawlers excluded from that edge block. Other WAF rules can still interfere.
Reload the public robots.txt URL after saving. Check the served managed section and your own rules together. Do not edit a generated section in WordPress and expect that to change the setting Cloudflare produces.
Cloudflare’s Bot Preference Sync configuration
Step 6 Correct the rule responsible and retest
In our fictional example, robots.txt allows the public service page and OAI-SearchBot is set to Allow. A matching security event shows that a broad challenge rule catches its request. Changing the training preference would not fix that cause.
Ask the person managing Cloudflare to narrow the identified rule or its exception so the intended legitimate crawler can reach the affected public content. Keep the existing training policy unless the evidence identifies that policy as the cause.
Use verified identity or current provider IP ranges where appropriate. A user-agent name can be copied, so an exception based only on text containing Googlebot or OAI-SearchBot is weak. Cloudflare provides examples using its verified-bot field, but that category includes other bots too; choose the scope your policy needs.
Cloudflare’s example for allowing verified search bots
Do not disable the whole firewall or apply a site-wide “skip all security” rule as the routine fix. Keep the correction tied to the rule, crawler and public pages you intend to allow. If the host or a WordPress plugin created the restriction, correct it there instead.
Retest the same URLs and settings
- Reload the public robots.txt and key pages. Confirm the intended text or page content is served, including necessary resources. Clear only the relevant cached response if it still contains the old output.
- Repeat the Search Console live test. Compare it with the earlier result. Request indexing for a corrected important page where appropriate, without treating the request as a guarantee.
- Review requests made after the change in Cloudflare and hosting logs. Confirm that genuine intended crawler requests reach the correct page, while the training restrictions and private-page protections still match your policy.
- Record the before-and-after evidence and review again after subsequent crawler activity. A successful browser visit or changed dashboard toggle alone is not a completed crawler retest.
OpenAI says robots.txt changes can take about 24 hours to affect its search systems. This does not promise a crawl or citation within a day.
Roll back if the correction causes a problem
Restore the saved rule expression, action and enabled state, or the previous WordPress or robots.txt setting. Restore any related Bot Preference Sync choice too if you changed it. Avoid reversing unrelated settings.
Clear the relevant cached response if necessary, then reload the same pages and rerun the tests. Confirm that the previous state is actually served. Record the rollback time and the remaining issue, and pass the saved request evidence to the person who manages the site.
Keep a short access-check record
Use one line per tested URL. Do not mark a crawler “passed” unless you have evidence for that crawler or test; write “Not observed” where genuine activity is missing.
| URL or path | Before | Change and time | Retest evidence |
| robots.txt | Served rules or error | Responsible layer and exact edit | New public response |
| Main service page | Fetch or challenge result | Rule identifier or page setting | Live test plus actual request |
| Guide or product page | Fetch and indexing checks | Exact correction | Returned content and resources |
| Contact page | Public access and form status | Any related adjustment | Page and successful form test |
A crawler request is not an AI citation, and a citation is not a visit or conversion. After access works, use the reporting guide to assess visibility and business results separately.
How to Track AI Search Visibility with Free Tools
A durable crawler access checklist
- Decide separately which search, training and user-directed access you want.
- Read the robots.txt response actually served, including any Cloudflare-managed directives.
- Check WordPress visibility, page indexing settings and actual returned content.
- Use live tests and real request evidence to identify the restriction and the layer responsible.
- Make one scoped correction, preserving a copy of the earlier state.
- Retest access and retained restrictions; roll back and retest again if the change causes a problem.
Fix access problems before drawing conclusions about content performance. Once useful public pages are reachable, search engines and assistants can consider them under their own eligibility and selection systems.
Sources and further reading
Cloudflare — Mixed-use crawlers and Disallow AI Training
OpenAI — Crawler documentation
Cloudflare — Bot Preference Sync and robots.txt
Cloudflare — Security Analytics navigation
Cloudflare — Manage AI crawlers
Cloudflare — Analyse AI traffic
Cloudflare — AI Crawl Control and WAF
Cloudflare — Detect a Challenge Page response
Cloudflare — Verified search bot rule example
Google — robots.txt introduction
Google — Crawler and product-token definitions
Google — Generative AI search requirements
WordPress — Generated robots.txt output
Documentation reviewed on 12 October 2026. Follow the linked current guidance if dashboard labels or crawler controls change.